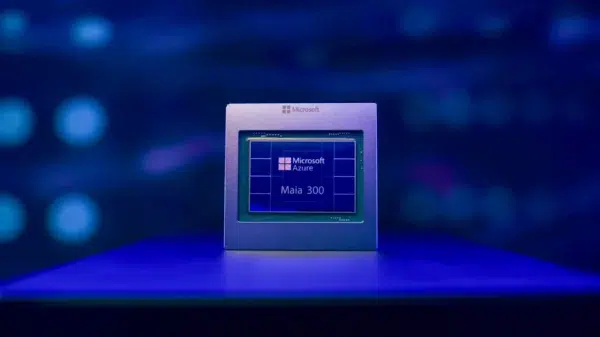



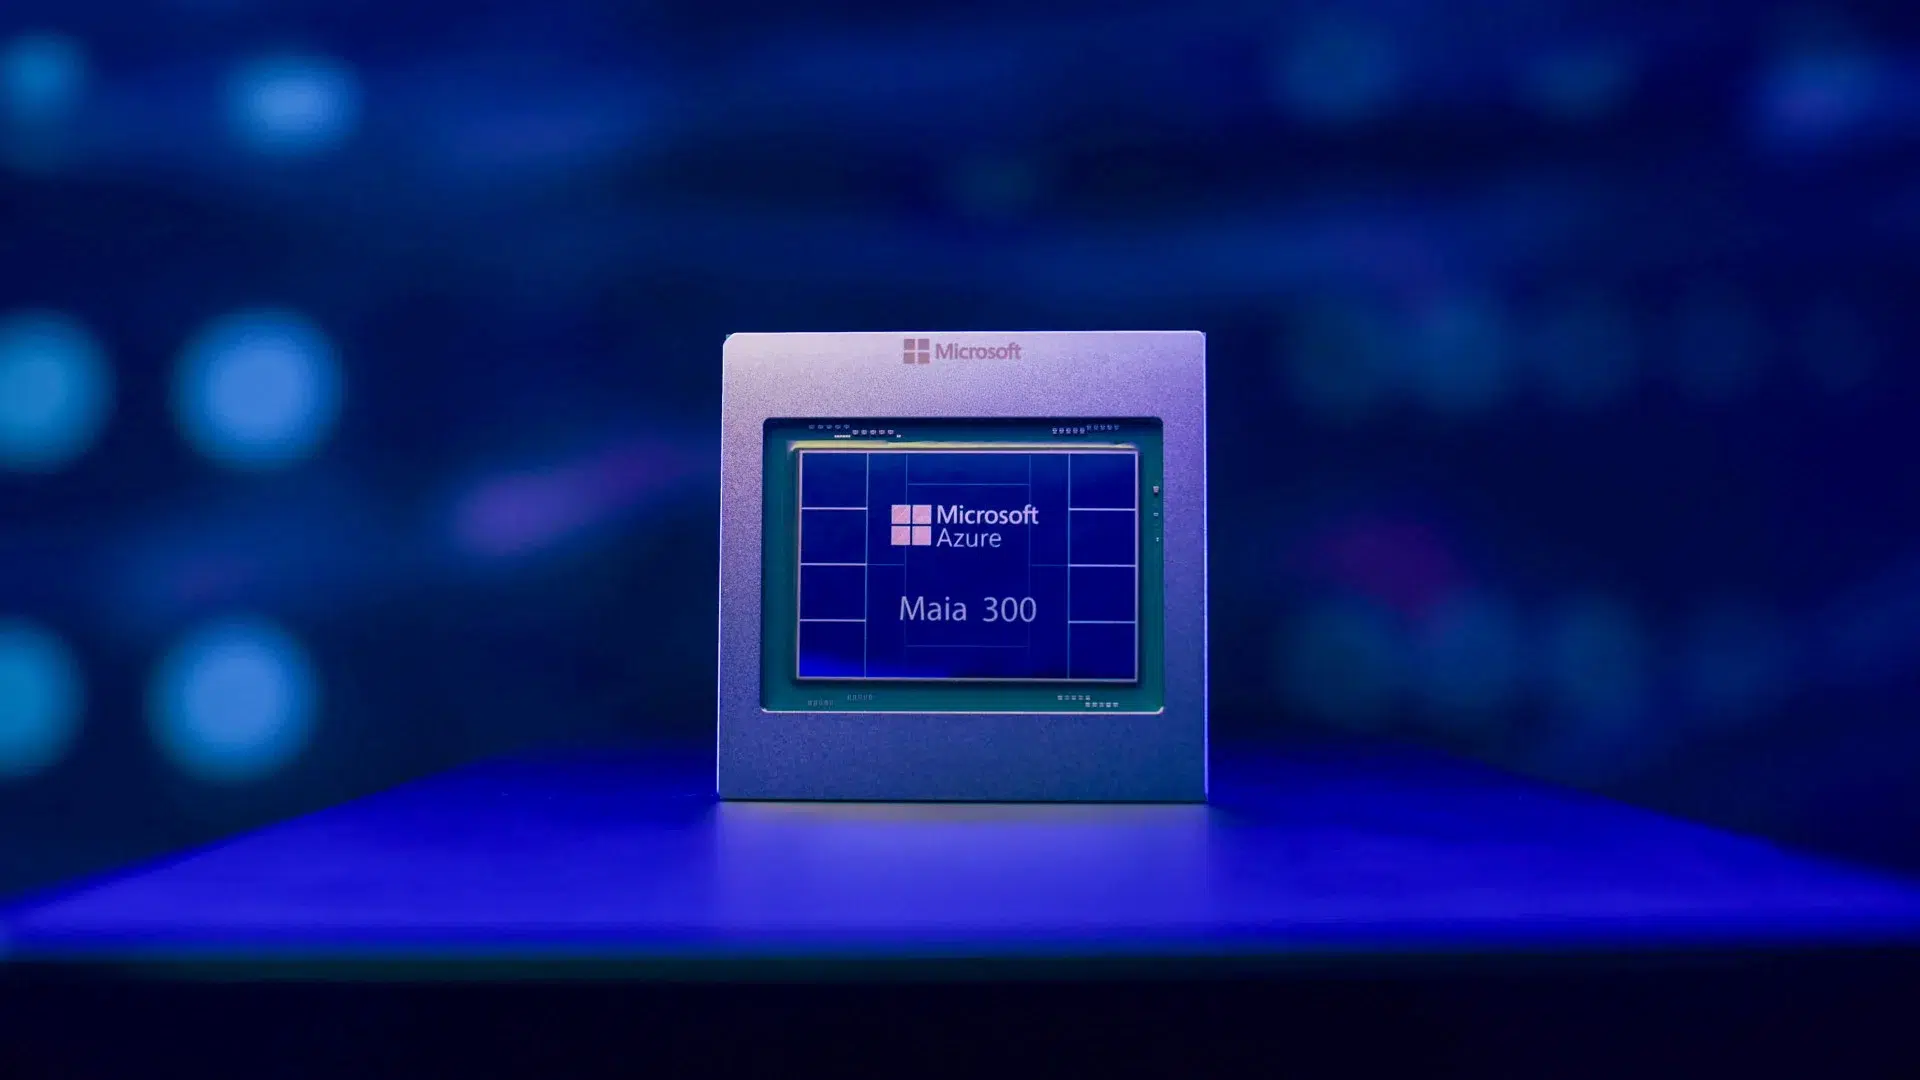
Microsoft has introduced Maia 300, its third-generation in-house artificial intelligence accelerator, designed to improve the efficiency and performance of large language model inference across its Azure infrastructure.
The chip combines advanced compute chiplets manufactured using TSMC’s N2P process with eight HBM4 memory stacks, delivering 288GB of memory capacity and 18TB/s of bandwidth per accelerator. Microsoft says the architecture can deliver up to seven times the rack-scale token throughput of its predecessor, Maia 200, when configured with 96 accelerators.
The announcement highlights Microsoft’s strategy to develop its own AI infrastructure as demand for computing power grows across services such as Microsoft Copilot, GitHub Copilot and Microsoft Foundry.
Maia 300 Targets Greater AI Efficiency
Microsoft is making its homegrown Maia 300 chip the primary engine for AI inference
Microsoft’s Maia 300 architecture separates compute, memory-controller and input/output functions across multiple chiplets. This approach allows the company to optimize different components for processing performance, memory bandwidth and cost.
The system also incorporates a Software Defined Locally Accessed Dataflow Architecture, which gives compilers greater control over data placement, direct memory access and synchronization across local memory, compute engines and networking components.
According to Microsoft executives Rani Borkar and Saurabh Dighe, Maia 300 delivers more than 2.5 times the performance per watt of Maia 200 in addition to its higher rack-level throughput. The company’s broader objective is to increase the amount of AI processing delivered for each unit of energy, memory and spending.
A fully configured rack contains 96 accelerators arranged across 24 four-accelerator trays, with a power requirement of 167 kilowatts. Liquid cooling handles more than 80% of the rack’s thermal load.
Microsoft’s design can also scale beyond individual racks. An optical interconnect tier can link as many as 12,288 accelerators across 128 racks into a single superpod, with up to 750GB/s of cross-rack bandwidth per chip.
Microsoft Moves to Strengthen Its AI Infrastructure
The Maia 300 launch comes as major technology companies expand their investments in custom AI processors to reduce reliance on third-party chip suppliers, particularly Nvidia.
Amazon is developing its Trainium accelerators, Google has its TPU platform, and Meta continues to advance its MTIA chips. Microsoft’s latest release positions its own hardware program alongside these competing efforts, particularly in the market for inference, where AI models generate responses to user requests.
Reporting cited by The Next Web indicates that Microsoft ordered approximately 300,000 Maia 300 chips from TSMC. The reported order provides a potential indication of the scale of its ambitions, although Microsoft’s architecture announcement does not specify production volumes or confirm the reported order.
Independent Performance Testing Remains Outstanding
Despite the performance figures disclosed by Microsoft, independent third-party benchmarks for Maia 300 have not yet been published. United Press International also noted that the company’s claim of a 40% improvement in tokens processed per megawatt-hour has not been independently verified.
Microsoft has outlined a 2027 production timeline in its broader announcement, but the architecture post does not identify which products will receive the chips first or provide a specific deployment volume.
The distinction matters because theoretical specifications and manufacturer benchmarks do not necessarily translate directly into performance across real-world AI workloads.
Maia 300 nevertheless represents a significant step in Microsoft’s effort to build more of its AI computing stack in-house. Its commercial impact will depend on how effectively the hardware performs at scale, how widely it is deployed across Azure and whether its efficiency gains can compete with established accelerator platforms.